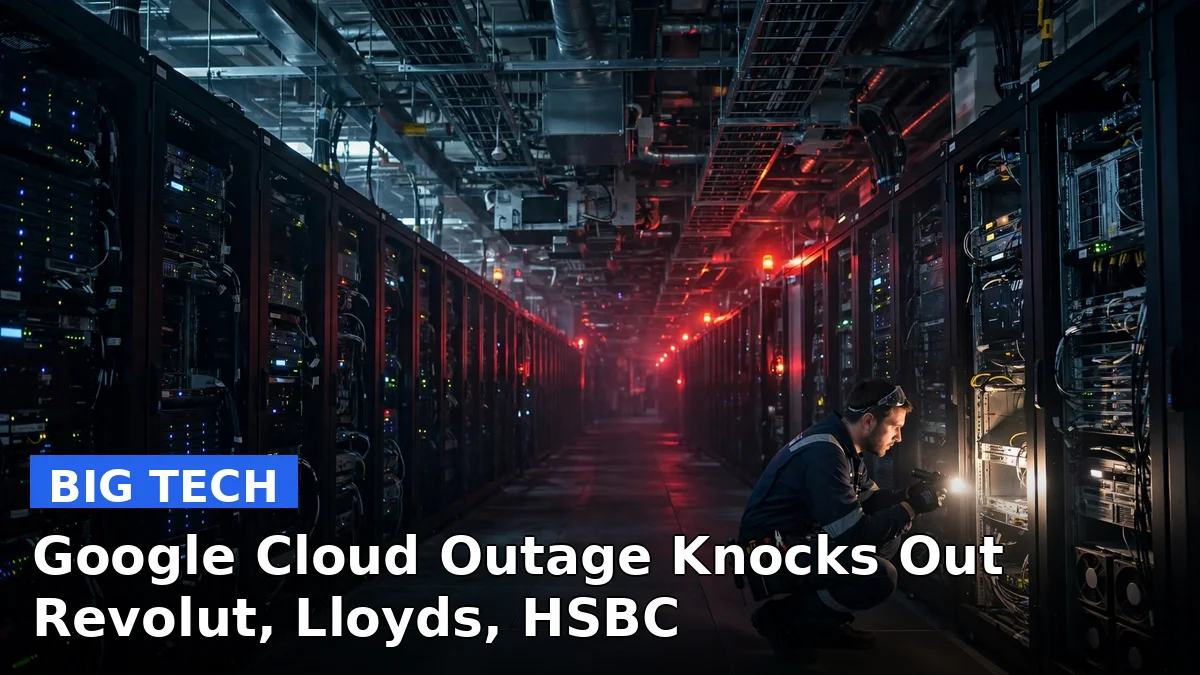
A power failure inside one of Google’s London data centers knocked out banking apps, postal services and property websites across the UK on Tuesday morning — and, in at least one case, across the entire world.
Google Cloud said “multiple services” in its europe-west2 region, which covers London, began experiencing “elevated errors and intermittent network failures” at 6:08 a.m. local time (2:08 a.m. ET) on October 20. In a later update, the company blamed “a power event we had suffered” and said the problem had been mitigated, with full recovery “tentatively” expected by 2 p.m. local time, or 9 a.m. ET.
For several million people, though, the damage was already done. The digital bank Revolut, which runs on Google Cloud infrastructure, saw its services go down worldwide. Card payments, bank transfers, ATM withdrawals, its trading platform and even customer sign-ins were all disrupted. Lloyds and HSBC, two of Britain’s biggest high-street banks, reported that customers were having trouble with their apps and online banking. Royal Mail, property site Rightmove, delivery firm DPD and telecom company BT also appeared on the outage tracker Downdetector’s list of affected services.
Inside the Google Cloud outage: one zone, and the cascade
The Register reported that the fault was concentrated in europe-west2-b, one of the three availability zones that make up Google’s London region. The idea behind zones is straightforward: if one fails, workloads shift to the others. That’s the theory, anyway.
In practice, plenty of services don’t run across multiple zones. One Reddit user watching the outage unfold summed it up bluntly: “oh man the classic one zone takes a nap and your non-HA service is in it.” Google’s own status page listed BigQuery Data Transfer Service, Cloud Filestore, Cloud Run, App Engine, Cloud NetApp Volumes, Google Kubernetes Engine and Managed Service for Apache Kafka among the impacted services, and told customers there were “no workarounds for now.”
“Our engineering team continues to investigate the issue,” Google said in its status update. “We apologize to all who are affected by the disruption.”
Revolut took the worst of it
No company felt the outage more directly than Revolut. The digital-only bank confirmed in a statement that “multiple services” had been affected, including card payments, transfers, ATM withdrawals, its trading platform and sign-ins — and that the problems extended beyond Britain to its global customer base.
The bank was quick to reassure customers on the one point that matters most. “We can confirm that all our customers’ money and data are safe,” a Revolut spokesperson said, adding that the bank had “been working to fix the issue since it was identified this morning” and apologizing “to anyone affected and for any inconvenience caused.”
Lloyds struck a similar note. “Our app is online and customers can log in normally, though we understand some are having issues with certain online services this morning,” the bank said, noting it was “aware of similar issues affecting other organisations.” HSBC said its customers were experiencing “difficulties accessing our services” and that it would “monitor the situation, which is also affecting other organisations.”
Why this keeps happening in London
This isn’t the first time the europe-west2 region has made headlines for the wrong reasons. In July 2022, a power and cooling failure in a different zone of the same region, europe-west2-a, disrupted Google Cloud services for 18 hours and 23 minutes — Google’s own postmortem later admitted traffic had been inadvertently rerouted away from all three availability zones. In August 2024, a power outage affecting networking equipment in the region caused about 40 minutes of connectivity problems.
Tuesday’s incident will almost certainly trigger another difficult postmortem. The uncomfortable question isn’t why a power event happened — data centers lose power — but why so much of Britain’s financial plumbing ran through infrastructure that couldn’t absorb it.
The bigger picture
Dr Amro Al-Said Ahmad, a computer science lecturer at Keele University, told The Times the outage “highlights the dependency effect of modern cloud ecosystems.” When a core cloud region fails, he said, the damage “extends far beyond the directly affected services” as cascading failures ripple through everything built on top.
That’s the real story here. Revolut didn’t break — Google Cloud did, and Revolut broke with it. The same goes for Lloyds, HSBC and Royal Mail. Modern banking increasingly rents its foundation from three or four American hyperscalers, and when one of them has a bad morning, the morning gets bad for everyone downstream.
Regulators in the UK have been warning about exactly this concentration risk for years. The Bank of England has been pushing “operational resilience” rules that require financial firms to keep critical services running even when their suppliers fail. Incidents like Tuesday’s are the reason those rules exist — and they raise an awkward question about whether the resilience requirements are actually being met.
Google hasn’t yet published a full root-cause report, and one will presumably follow in the coming days. Until then, the lesson is one the industry keeps relearning: the cloud is just somebody else’s computer, and somebody else’s computer can lose power too.
Frequently asked questions
What caused the Google Cloud outage on October 20, 2026?
Google said its London region (europe-west2) suffered a “power event” at a data center starting at 6:08 a.m. GMT. The failure caused elevated errors and intermittent network failures across multiple cloud services.
Which companies were affected by the Google Cloud outage?
Revolut was hit hardest, with card payments, transfers, ATM withdrawals and sign-ins disrupted worldwide. Lloyds, HSBC, Royal Mail, Rightmove, DPD and BT also reported customer-facing problems, according to Downdetector and company statements.
Was Revolut customers’ money safe during the outage?
Yes. Revolut said “all our customers’ money and data are safe,” describing the incident as a service disruption caused by an upstream infrastructure failure rather than a security breach.
When did Google Cloud services recover from the outage?
Google said the power event had been mitigated and services were “tentatively” expected to fully recover by 2 p.m. local time (9 a.m. ET) on October 20, though intermittent errors continued through the morning.
Sources: Bloomberg Technology, Economic Times, The Times, The Register, AFP